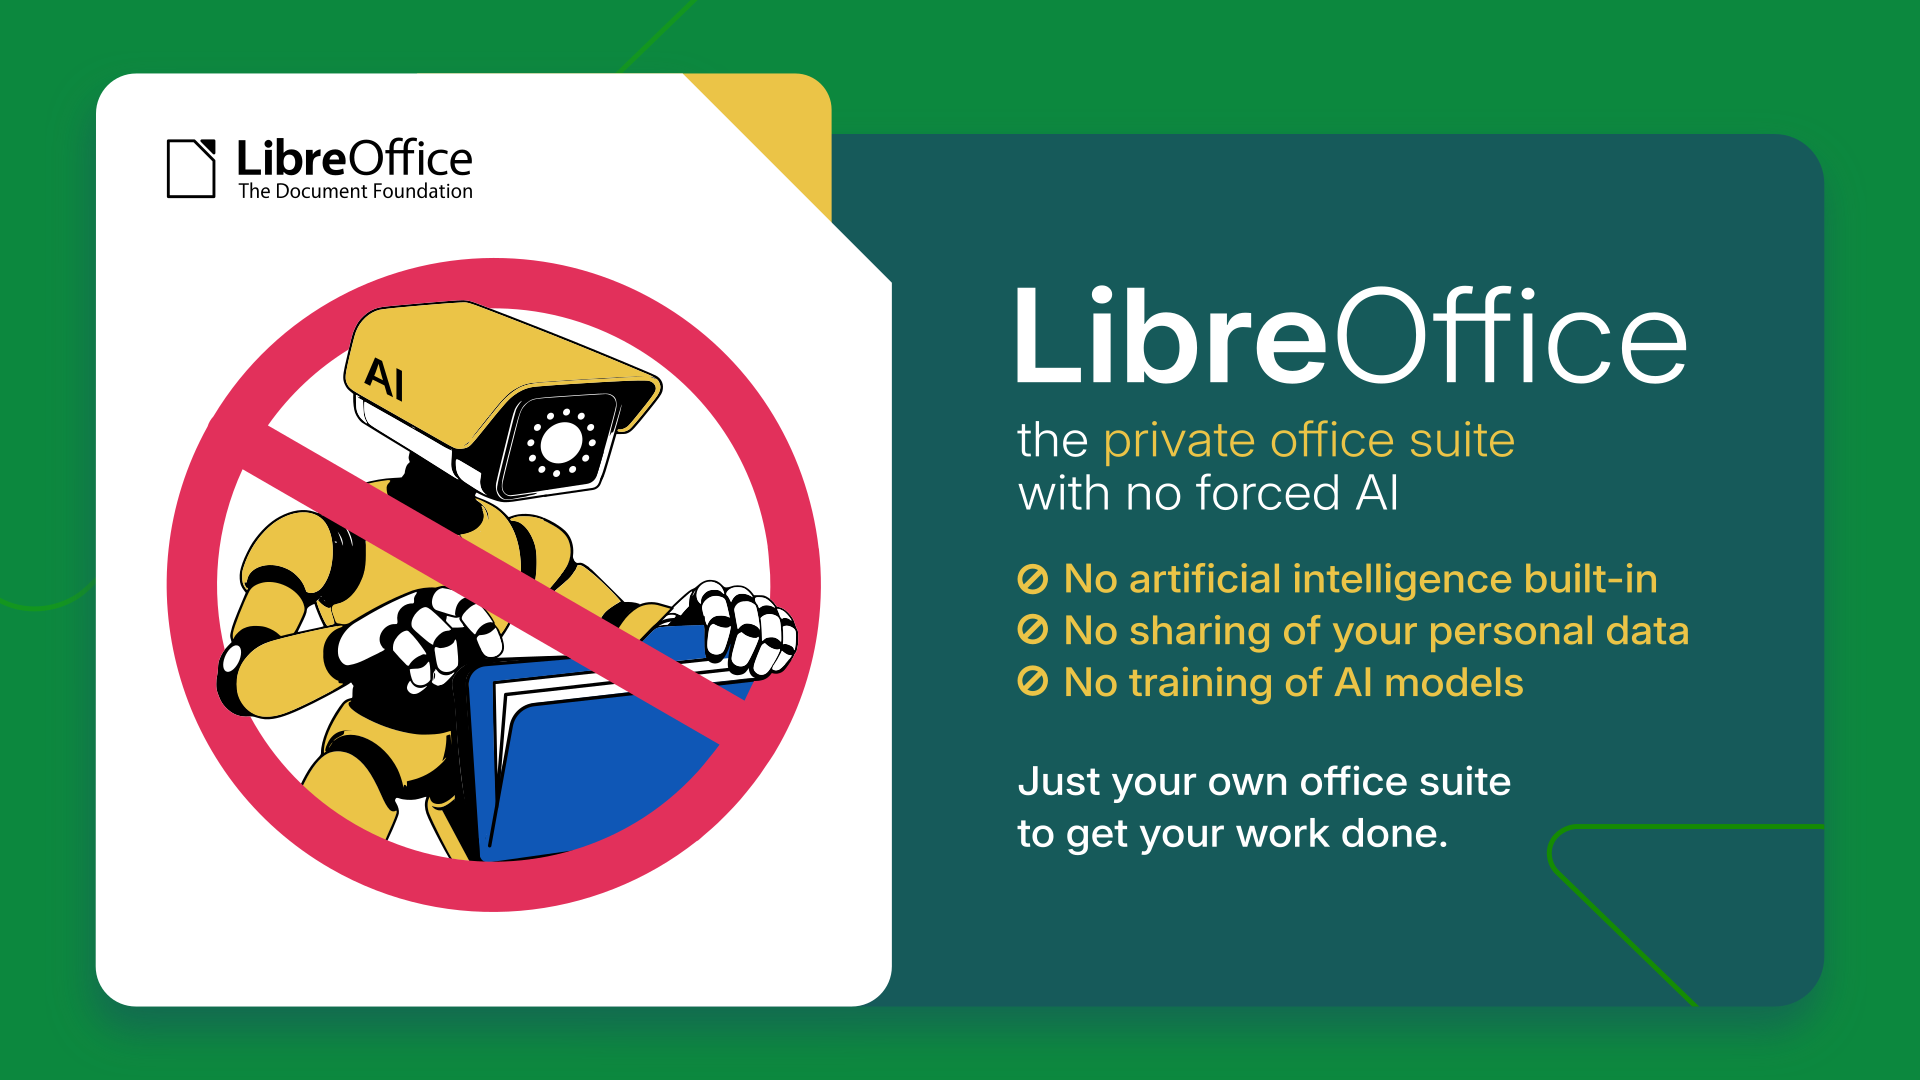
Yes, no (built-in) AI is now a feature
-
@libreoffice fantastic! Now I just need libre office to stop crashing when I open it

-
@wobweger @libreoffice @grvsmth @moskitokoenig
It's still coded using AI, same as what Debian just decided to do.
https://github.com/LibreOffice/core/commit/70c7f6ba49cfc506fc47dac32af98976ecf33cf8
https://github.com/LibreOffice/core/commit/42cdc47554fa746baa863860143fc81fe8bb1c80
https://github.com/LibreOffice/core/commit/7c0d875aca090de4f4d1164578683c0b7e0c6040
-
@cosmin @argv_minus_one Ah, another high-quality Mastodon discussion. Again: No core developers use LLMs. We rely on contributions from the wider community and don't explicitly list tools people can't use – but we do require people disclose when they use LLMs and generally discourage the practice. We carefully review submissions by contributors to make sure the code quality is good and that the patch author understands their own code. LLMs are prohibited for students. That is not "slop".
-
@libreoffice fantastic! Now I just need libre office to stop crashing when I open it
@CorvidCrone Obviously, that shouldn't be happening, but without any details about your setup (computer type, operating system, LibreOffice version etc.) it's hard for us to say what the problem could be...
-
Yes, no (built-in) AI is now a feature
https://blog.documentfoundation.org/blog/2026/09/03/yes-no-ai-is-now-a-feature/
@libreoffice In fact, it's the other way around: AI has built-in you
https://simonwillison.net/2026/Sep/1/codex-libreoffice/ -
@worik @Garonenur @argv_minus_one @wobweger @libreoffice @moskitokoenig I don't come on Mastodon for grandiose pronouncements based on one individual's experience.
@grvsmth @Garonenur @argv_minus_one @wobweger @libreoffice @moskitokoenig
Golly!
What do you expect when communicating?
It is a shame if you cannot tolerate disagreement
I have no problem with your opinions and POV, I disagree with some of it
For bubbles of agreement I would have stayed on Facebook!
-
@argv_minus_one @worik @wobweger @libreoffice @moskitokoenig "Thorough" is the last thing I associate with commands produced by a random text generator.
@grvsmth @argv_minus_one @wobweger @libreoffice @moskitokoenig
I do urge you to experiment with them. It is a mischaracterisation to call them "random text generators".
-
@worik @argv_minus_one @wobweger @libreoffice @grvsmth @moskitokoenig

How can the: "here is the stochastic average of the training data" be of better quality?
That is not how LLMs work.The code quality is shit, especially without rigorous human supervision.
@Garonenur @argv_minus_one @wobweger @libreoffice @grvsmth @moskitokoenig
Your comment about their output being shit is two years out of date
These days the code they produce is often very good.
Times are changing, and the development since 2022 has been astounding
The last nine months alone has seen huge advances.
-
Yes, no (built-in) AI is now a feature
https://blog.documentfoundation.org/blog/2026/09/03/yes-no-ai-is-now-a-feature/
@libreoffice https://blog.documentfoundation.org/blog/2026/08/21/there-is-no-best-interface/ Was this blog post written with the help of AI?
-
@grvsmth @Garonenur @argv_minus_one @wobweger @libreoffice @moskitokoenig
Golly!
What do you expect when communicating?
It is a shame if you cannot tolerate disagreement
I have no problem with your opinions and POV, I disagree with some of it
For bubbles of agreement I would have stayed on Facebook!
What you said was a factual assertion, not an opinion. One that is not supported by available evidence.
Nor is it supported even by theory. LLMs work by making predictions based on statistical analysis of what humans have previously done. Therefore they cannot surpass even the average human, let alone the best.
Which is why I say your admiration of LLMs speaks not highly of them, but poorly of you. It proves that you're below average.
-
What you said was a factual assertion, not an opinion. One that is not supported by available evidence.
Nor is it supported even by theory. LLMs work by making predictions based on statistical analysis of what humans have previously done. Therefore they cannot surpass even the average human, let alone the best.
Which is why I say your admiration of LLMs speaks not highly of them, but poorly of you. It proves that you're below average.
And your assertion was indeed quite grandiose.
“From now on the best code will be aided by LLMs in its construction. That is true now.” That's literally what you said. Unadulterated arrogance, supported only by vague claims of professional experience that I'm fairly sure you don't actually have (because if you did, you'd have brought receipts).
Perhaps that sort of behavior was welcome on Facebook, but you'll find little love for it here.
-
What you said was a factual assertion, not an opinion. One that is not supported by available evidence.
Nor is it supported even by theory. LLMs work by making predictions based on statistical analysis of what humans have previously done. Therefore they cannot surpass even the average human, let alone the best.
Which is why I say your admiration of LLMs speaks not highly of them, but poorly of you. It proves that you're below average.
@argv_minus_one @grvsmth @Garonenur @wobweger @moskitokoenig
Argumentum ad hominem ignored
I asserted that working on code is what (one thing) LLMs are good for.
I have been watching closely as LLMs and the harnesses have developed and they have astounded me.
There is little useful theory. That "text completion" could do all this is very surprising and I know of no theory to explain it
https://youtu.be/_MwMLPmMccs?si=RSTP2TcZCqmNGxX- is a short talk by Greg Kroah-Hartman you may find helpful.
-
@grvsmth @argv_minus_one @wobweger @libreoffice @moskitokoenig
I do urge you to experiment with them. It is a mischaracterisation to call them "random text generators".
I have, on several occasions.
One that stands out is when I asked a bot (I think Claude Haiku) a question about a programming topic I'm not entirely familiar with. It gave me 10 answers, 4 of which were obviously wrong based on the self-contained test case I presented it with, and 4 more of which immediately proved wrong upon cursory testing.
It was obvious that the bot was just making s**t up and had no idea what it was talking about.
-
I have, on several occasions.
One that stands out is when I asked a bot (I think Claude Haiku) a question about a programming topic I'm not entirely familiar with. It gave me 10 answers, 4 of which were obviously wrong based on the self-contained test case I presented it with, and 4 more of which immediately proved wrong upon cursory testing.
It was obvious that the bot was just making s**t up and had no idea what it was talking about.
2 of the answers were correct, so at least it wasn't a complete waste of my time.
But if I got 2 out of 10 questions wrong on a test at school, I wouldn't have been proclaimed a star pupil that everyone else has to keep up with. I'd have gotten an F, and then I'd have gotten a stern talking-to by my parents.
-
I have, on several occasions.
One that stands out is when I asked a bot (I think Claude Haiku) a question about a programming topic I'm not entirely familiar with. It gave me 10 answers, 4 of which were obviously wrong based on the self-contained test case I presented it with, and 4 more of which immediately proved wrong upon cursory testing.
It was obvious that the bot was just making s**t up and had no idea what it was talking about.
@argv_minus_one @grvsmth @wobweger @libreoffice @moskitokoenig
That is the exact opposite of my experience
You sure that you are not making it up?
-
@Garonenur @argv_minus_one @wobweger @libreoffice @grvsmth @moskitokoenig
Your comment about their output being shit is two years out of date
These days the code they produce is often very good.
Times are changing, and the development since 2022 has been astounding
The last nine months alone has seen huge advances.
More like two days. I frequently get sent slop by my coworkers.
No, it isn't. Not even remotely.
Yes, they are…in that we are speeding into an apocalypse of automated incompetence and consequent project collapse. I now fear deeply for the future, because of people like you.
The last nine months have been catastrophic.
-
@argv_minus_one @grvsmth @Garonenur @wobweger @moskitokoenig
Argumentum ad hominem ignored
I asserted that working on code is what (one thing) LLMs are good for.
I have been watching closely as LLMs and the harnesses have developed and they have astounded me.
There is little useful theory. That "text completion" could do all this is very surprising and I know of no theory to explain it
https://youtu.be/_MwMLPmMccs?si=RSTP2TcZCqmNGxX- is a short talk by Greg Kroah-Hartman you may find helpful.
Your being astounded does not mean LLMs have surpassed humans, only that they've surpassed you.
Anyway, Greg K-H is talking about using LLMs to find bugs, like a static analyzer. That's grand and all, but you're talking about vibe code, and that's not what he's talking about.
-
I have, on several occasions.
One that stands out is when I asked a bot (I think Claude Haiku) a question about a programming topic I'm not entirely familiar with. It gave me 10 answers, 4 of which were obviously wrong based on the self-contained test case I presented it with, and 4 more of which immediately proved wrong upon cursory testing.
It was obvious that the bot was just making s**t up and had no idea what it was talking about.
@argv_minus_one @grvsmth @wobweger @libreoffice @moskitokoenig
> One that stands out is when I asked a bot (I think Claude Haiku) a question about a programming topic I'm not entirely familiar with. It gave me 10 answers, 4 of which were obviously wrong based on the self-contained test case I presented it
I am curious.
May I have the question? I can try it out here
-
Your being astounded does not mean LLMs have surpassed humans, only that they've surpassed you.
Anyway, Greg K-H is talking about using LLMs to find bugs, like a static analyzer. That's grand and all, but you're talking about vibe code, and that's not what he's talking about.
I'm also not impressed with the high false-positive rate and psychologically-manipulative behavior Greg describes having experienced in his interactions with bots. Maybe he finds that tolerable, but I don't.
-
@Garonenur @argv_minus_one @wobweger @libreoffice @grvsmth @moskitokoenig
Your comment about their output being shit is two years out of date
These days the code they produce is often very good.
Times are changing, and the development since 2022 has been astounding
The last nine months alone has seen huge advances.
@worik @argv_minus_one @wobweger @libreoffice @grvsmth @moskitokoenig I have to read and review the code right today.
And it sucks.
It reuses old fashioned paradigms, because the old shit is more prevalent in the training data.
AND the users of those LLMs all start to become lazy and just believe what hallucinations the machine dishes them.
Code quality was terrible before, it will only go down now.